Contents
- How to read the index report in Google Search Console to find where the problem is
- Quickly check the three technical issues that often keep Google from indexing posts
- Check page quality before blaming Google
- How to use URL Inspection to request indexing correctly
- How to handle the most common indexing errors in Search Console
- After fixing, validate again and track for how long
- How to prevent repeated indexing errors on WordPress and content sites
- Frequently asked questions about fixing Google Search Console indexing errors
If Google Search Console reports that a URL has not been indexed, don’t rush to request indexing again right away. Check the status under Indexing > Pages first, because the page may be in `Crawled – currently not indexed`, `Page is not indexed`, `Excluded URLs`, or `Indexed, though blocked by robots.txt`. For new sites, WordPress sites, or pages that have just been updated, these issues are fairly common.
How to fix Google Search Console indexing errors effectively means identifying the real cause first: blocked by robots.txt, tagged noindex, thin content, or simply needing a reindex request. This section focuses on how to check quickly, fix the right issue, and know when to use URL Inspection to resubmit.
How to read the index report in Google Search Console to find where the problem is
The index report in Google Search Console shows which URLs Google has processed, which URLs were excluded, and why they were excluded. To find where the problem lies, go to Indexing > Pages, look at the first status group that appears, then compare the affected URLs within each group.
Which statuses should be handled first, and which can be ignored for now?
Prioritize important URLs that are blocked or not indexed, because these directly affect traffic and search visibility. A new blog post, product page, or sales landing page that is in “Page is not indexed” status should be fixed immediately; by contrast, tag pages, internal search pages, or archives can often remain excluded if they do not need indexing.
When reading the Indexing report, classify by impact:
- Important URLs that are blocked or excluded: handle first.
- URLs that should be indexed but are not yet indexed: investigate further.
- Secondary URLs, thin-content pages, or pages with no search value: can be ignored for now.
A useful workflow tip is to take a screenshot of the status before making changes. After you validate the fix, compare the same URL group again to see whether the change actually had an effect.
What signs show the issue is with robots.txt, noindex, or canonical?
If Google is not indexing the page, look at the exclusion reason to narrow down the cause before making changes. Robots.txt crawl blocks often appear with a status like “Indexed, though blocked by robots.txt,” while a meta noindex tag allows the URL to be crawled but not indexed.
A wrong canonical is often seen when Google chooses a different URL as the canonical version, especially when a post exists with and without parameters, or when category pages and article pages overlap in intent. If the URL returns an error code, you will see that the page cannot be indexed even though it exists in the system. With thin content, Google may place it in the crawled but not indexed group instead of showing a clear technical error.
Quick checks:
- Open URL Inspection to see the current index status.
- Check robots.txt at /robots.txt.
- View the page source to find noindex and canonical.
- Match the URL showing the error with the canonical URL you want Google to index.
Quickly check the three technical issues that often keep Google from indexing posts
The three technical points to check immediately when Google does not index a post are robots.txt, the meta noindex tag, and canonical. A single mistake can prevent crawling, indexing, or cause Google to choose the wrong canonical URL. The safe approach is to check each point against the exact URL that is having the issue, rather than removing blocks across the entire site.
How to check whether robots.txt is accidentally blocking crawl
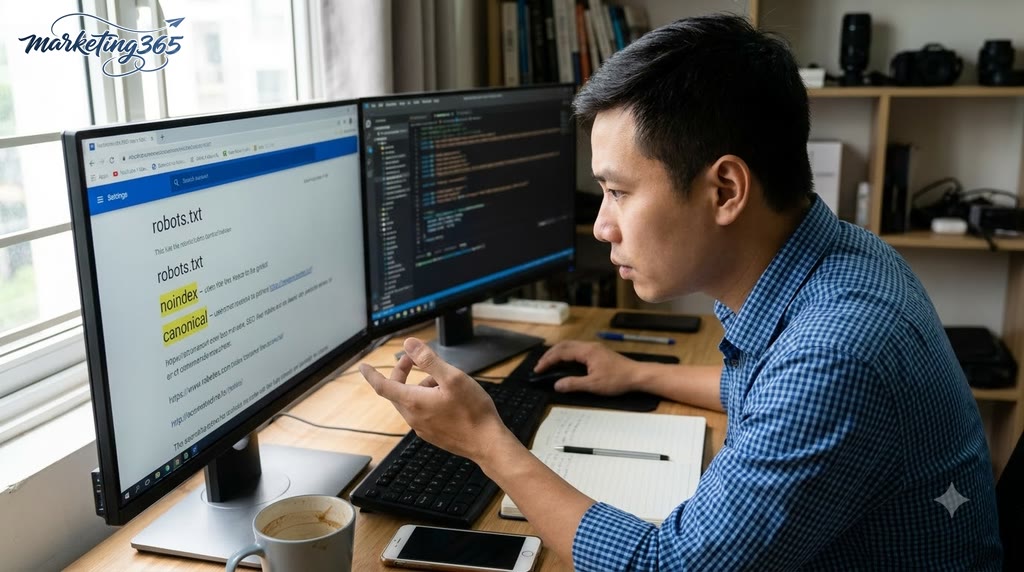
Open `ten-mien-cua-ban/robots.txt` first. If you see a `Disallow` line applying to `/`, `/bai-viet/`, or the exact folder containing the affected URL, Google may be blocked from crawling it. This often happens when an SEO plugin is enabled, a hosting template configuration is installed, or development mode is left on after the site goes live.
It is important to distinguish clearly: robots.txt blocks crawling, while noindex blocks indexing. A URL may still appear as “Indexed, though blocked by robots.txt” if Google knew the URL from before, but new content will not be crawled again. So if a post has not been indexed, check whether the `Disallow` line is blocking the correct path.
How to fix robots.txt:
- Only remove blocking for the exact folder or URL pattern that needs indexing.
- Keep blocking rules for admin pages, cart pages, or internal areas.
- Save the file, then recheck the URL using the URL inspection tool in Google Search Console to confirm Google can read the page.
Check the meta noindex tag and canonical page before requesting reindexing
The meta noindex tag will prevent Google from indexing the post, while a wrong canonical can cause Google to choose a different URL as the canonical version. These two issues are easy to confuse because the page still opens normally in the browser.
Quick checks:
- View the page source and look for `meta name=”robots”` or `noindex`.
- Use URL Inspection to see which page Google is reading and the canonical declared by the system.
- Compare the canonical with the actual post URL; if the canonical points to a category page, a parameterized page, or another post, it needs to be fixed.
How to fix it:
Read more: Common WordPress SEO Errors and How to Check Them Quickly
- If the post should be indexed, remove `noindex` on that URL or from the group of pages that was tagged incorrectly.
- If the canonical is wrong, change it to the correct canonical URL for that post.
- After fixing it, use URL Inspection to request reindexing and monitor the status under Indexing > Pages.
When fixing Google Search Console indexing errors, always correct the root cause first and only then request indexing again. Doing it the other way around only wastes time and may cause Google to keep ignoring the old URL.
Check page quality before blaming Google
Google often skips a page when quality signals are not clear enough, even if the technical setup is correct. That is why the how to fix Google Search Console indexing errors approach should start with checking page quality before sending a reindex request.
A page is more likely to be skipped when the content is thin, duplicated, the title does not match search intent, the page loads slowly, rendering fails, or internal links are missing. With WordPress, I usually quickly review the post URL, the opening section, the featured image, then open the Indexing > Pages report to compare statuses such as Crawled – currently not indexed or Page is not indexed. If a newly published page has no internal link from related posts, Google often needs more time to understand the topic.
Quick checklist before clicking request reindexing:
- Is the content deep enough to answer the query properly?
- Does it have an opening section that explains the topic right away?
- Is the post copied or too similar to other posts on the site?
- Does the page load slowly on mobile, especially with large images and heavy scripts?
- Are canonical, noindex, or robots.txt blocking it by mistake?
- Has the page been linked from related articles yet?
- Are Core Web Vitals showing clearly poor signals?
What signs show a page is not yet ready to be indexed well?
The clearest signs are that the page is too short, only a few paragraphs long, the title is vague, and the images lack context. When checking a new post that is not indexed, I often find a brand-new URL with no internal signals, or content that is identical to another post on the site. If you have clicked request index many times and still hear nothing back, that is usually a sign the page is not good enough for Google to prioritize.
What changes should be made before clicking request reindexing?
Prioritize fixing the parts that directly affect content understanding and indexing eligibility first.
- Add original content, examples, FAQs, or a clear explanation of the topic.
- Adjust the title and description to match search intent.
- Check canonical, the noindex tag, and robots.txt at ten-mien/robots.txt if crawl blocking exists.
- Add internal links from related pages to create internal signals.
- Review the template/theme if the page loads slowly or the content area is not fully rendered.
After making changes, use URL Inspection to request reindexing instead of clicking repeatedly while the page is still thin.
How to use URL Inspection to request indexing correctly
URL Inspection is a direct way to check a URL in Google Search Console to see whether the page can be indexed, and then decide whether to request indexing or wait for Google to crawl it naturally.
When should you request indexing, and when should you wait for Google to crawl naturally?
You should request indexing when you have just finished fixing an important page, such as a sales page, a main category page, or a post that already has traffic but is showing an indexing error. In this case, you have confirmed the content is ready and want Google to pick up the changes sooner.
You should wait for Google to crawl naturally for secondary pages, archive pages, pages still being edited, or URLs with no clear value yet. If the page may still change within a few hours, sending a reindex request now only means you will have to check it again and again. A good indexing decision is: the page is complete, indexable, not blocked from crawling, and the live version matches the version you just edited.
Checklist before clicking request index:
- The page content is complete.
- There is no longer a noindex tag.
- It is not blocked by robots.txt.
- The canonical points correctly.
- No further edits are needed within the next 24 hours.
What should you check in the URL inspection result before resubmitting?
The URL inspection result tells you how Google sees the page at the time of the live test, so you need to read it before sending the request again. If you skip this step, you may request indexing for a URL that is still blocked or for one where Google has chosen a different canonical.
Check four main points: whether the page can be indexed, whether it is blocked from crawling, what canonical Google selected, and whether the live version matches the edited version. For example, if the live test still shows old content, the change has not been deployed or the cache has not updated yet. If Google selects a different canonical, you need to fix the canonical URL first and only then request indexing.
The safe workflow is: check status → fix the issue → test again → request index → monitor the response. Once the issue has been resolved, use validate fix instead of spamming indexing requests. With Google Search Console indexing fixes, speed matters less than sending the right URL, in the right status, at the right time.
How to handle the most common indexing errors in Search Console
Read more: How to Use Google Search Console for Beginners
Indexing errors in Search Console need to be read by branch, because each status points to a different issue. Even though the page is not showing on Google in both cases, the fix may differ from content, robots.txt, canonical, to noindex.
What usually causes “Crawled – currently not indexed,” and how should it be fixed?
Crawled – currently not indexed means Google has crawled the URL but has not chosen to include it in the index yet. This often happens with new posts, thin content, duplicate content, weak internal linking, or insufficient quality signals.
Quick fix:
- Open URL inspection in Indexing > Pages to see when Google last crawled it.
- Add unique content, clarify the intent, and add internal links from related pages.
- Check whether the canonical, title, and opening section are too similar to many other pages.
- After fixing it, use URL Inspection to request indexing again.
If the page remains in this status after a few days, it is usually better to improve quality and usefulness rather than keep requesting indexing.
Is “Indexed, though blocked by robots.txt” dangerous, and how do you fix it?
Indexed, though blocked by robots.txt is a warning that the URL is already in the index but robots.txt is currently blocking Google from crawling it. This status is not necessarily dangerous, because in some cases the page was indexed earlier or discovered from another source.
The first thing to do is decide whether to keep or remove indexing for that URL. If you want the page to continue appearing on Google, remove the block in robots.txt at the correct path, usually /robots.txt, then check again with URL Inspection. If you do not want this page indexed, keep the block or switch to noindex for the correct purpose.
A common mistake is removing the block too quickly without checking whether the page should appear in search results at all. Doing that can cause Google to crawl a URL that should have stayed hidden.
How should “Page is not indexed” and “Excluded URLs” be read differently?
Page is not indexed usually means the page has not entered the index yet, while Excluded URLs is a group of URLs excluded for technical reasons or by Google’s choice. Both do not appear in search, but the Indexing > Pages report must be read based on the specific reason in each row.
For example, a URL may be excluded because the canonical points to another version, because of noindex, or because Google considers it a duplicate that does not need indexing. When you see Excluded URLs, do not make bulk changes. Open each URL in the report, check the main reason, then decide whether to keep it excluded or fix the issue.
For page is not indexed, prioritize checking content, crawlability, and linking signals first. For excluded URLs, prioritize checking canonical, noindex, and technical settings to avoid fixing a URL that was correctly excluded.
After fixing, validate again and track for how long
After fixing, validate again in Google Search Console right away and monitor the status for a few days before drawing conclusions. The how to fix Google Search Console indexing errors approach works best when you recheck the URL, submit Validate fix, and then see whether the error disappears across multiple URLs.
Which metrics should you track to know whether the fix worked?
Looking only at the index status is not enough. Open the Pages report or Indexing > Pages, compare the number of excluded URLs, the number of indexed URLs, the live test status in URL Inspection, and whether the page returns the correct canonical URL. If you just removed noindex, fixed robots.txt, or changed canonical, the canonical URL must be crawled again and the errors should decrease gradually, not just one URL turn green.
When should you go back and check from the beginning instead of waiting?
If indexing errors reappear across multiple URLs, the canonical is still wrong, robots.txt is still blocking crawl, or the content has not been improved enough, check everything from the beginning instead of waiting. With Google Search Console indexing fixes, the sign that you need to start over is when Validate fix has been submitted but the report does not show fewer errors after a few days, or when a group of pages repeats the same old pattern of errors. In that case, fixing each root cause and then validating again will be faster.
How to prevent repeated indexing errors on WordPress and content sites
The way to prevent repeated indexing errors on WordPress and content sites is to maintain a pre- and post-publishing check process instead of waiting for Google to report an error and then fixing it. With WordPress SEO, errors often return because of templates, noindex, WordPress robots.txt, or weak internal linking.
Minimum checklist before publishing an important page
The publishing checklist should be followed in the correct order so that important pages are not missed at the technical stage.
Read more: How to Read Google Search Console Reports Correctly
- Check that the URL has the correct slug and has not been duplicated or changed after sharing.
- Open the page visibility settings and make sure there is no noindex tag.
- Review canonical so it points to the correct main URL, especially when there are versions with or without a trailing slash.
- Add at least 1-2 internal links from related posts so Google can find the page faster.
- Review the content to make sure it has enough information, images, and files that do not block rendering.
- If it is an important page, use URL Inspection in Google Search Console to check indexing status.
A well-published page usually goes through all 6 of these steps before going live, especially when changing the theme or adding a new SEO plugin. If internal links are missing or the canonical is wrong, the page may be crawled but still end up in the Page is not indexed group.
What site changes can easily cause indexing errors to return?
Indexing errors often return after changes that affect the site’s crawl structure or templates.
Common breakpoints include changing the theme, installing a new SEO plugin, editing robots.txt, enabling WordPress’s noindex setting, changing permalinks, or moving the domain/subdomain. A single leftover noindex setting in a template can cause many child pages to be excluded at once.
When making major changes, review three things: the robots.txt file at /robots.txt, the post template, and the Indexing > Pages report in Search Console. Then check important URLs with URL Inspection, because that is the fastest way to see indexing errors return right after an edit.
Frequently asked questions about fixing Google Search Console indexing errors
This FAQ section helps quickly confirm the priority steps when handling indexing errors in Google Search Console. You should check in this order: URL Inspection, robots.txt, noindex, canonical, and only then request indexing.
What should you check first if Google is not indexing a new post?
Google often does not index a new post because the URL is blocked from crawling, has a noindex tag, is canonicalized to another URL, or does not yet have enough signals. Follow these 4 steps:
- Open Google Search Console > URL Inspection and paste the exact post URL.
- Check the “Page is not indexed” line and the Coverage section for the specific reason.
- Open ten-mien-cua-ban/robots.txt to see whether there is a `Disallow: /` line or a block on the folder containing the post.
- View the page source to find the `meta robots noindex` tag and the canonical tag pointing to the correct URL.
For example, a WordPress post may fail because an SEO plugin set `noindex` for the category, or the theme automatically generated a canonical to the archive page. After fixing it, click Request Index in URL Inspection to resubmit the URL.
Should you delete and republish the post to get Google to index it faster?
No, you should not delete and republish if the old URL still works, because you will lose crawl signals and existing links. The safer approach is to fix the indexing error on the current URL and then resubmit it.
Follow these 3 steps:
- Keep the same URL if the issue is only technical, such as noindex, robots.txt, or a wrong canonical.
- Adjust the content or configuration directly on the old post.
- Request Index and monitor the status under Indexing > Pages after 24 to 72 hours.
Only create a new URL when the old post has severe structural issues, a very poor slug, or has been blocked from indexing in a way that is difficult to fix. For example, a post duplicated by an incorrect import from a plugin like WP All Import usually needs content consolidation and the correct canonical, rather than repeated delete-and-republish cycles.
How long after fixing it will Google reindex the page?
Google does not have a fixed timeline, but many URLs will be crawled again within a few hours to a few days if the issue has been fully fixed. After resolving it, use Validate Fix in Search Console and check Indexing > Pages again.
The process should be:
- Fix the technical issue on the page.
- Click Validate Fix so Google checks it again.
- Use Request Index for the most important URL.
- Monitor the report for 3 to 7 days to see whether the status changes from error to valid.
If it still has not changed after 7 days, there is usually one of three remaining issues: low crawl budget, content that is too thin, or Google still choosing a different canonical URL. In that case, check the sitemap and internal links again to strengthen the URL’s signals.
For the official and latest guidance, you can also refer to documentation from Google Search Central.
You can also explore more practical marketing guides at https://marketing365.vn.
Content from marketing365 is created for SMEs, online store owners, and new marketers.