Contents
- 23,000 words in storage, 206,000 words on the page
- The first three measurements all produced the wrong list
- The only measurement left after the first three were rejected
- The culprit: missing block closers
- Once the render-time duplication was fixed, a second layer appeared
- Today’s recheck, and what I still owe
There is a kind of bug more annoying than a page crash: one that looks clean everywhere you check, but only readers can see it break. This is a record of one such case on marketing365.vn — a post that was duplicated nine times, even though the content stored in the database was a single copy, not a single extra word.
23,000 words in storage, 206,000 words on the page
I found it because I counted in the wrong place. While tallying the number of items in each post, I counted on the live page instead of in the stored content. One post returned a count nine times higher than the number I knew for certain was correct.
When I checked layer by layer, every layer looked clean. Reading the post content directly from the database: one copy, the right number of items. Running the block-rendering function from the command line: the same number of words. But opening the page in a browser showed a post body of 206,000 words, while the original was only 23,000.
This was the part that took me the longest: if you keep searching in the database, you will never see it, because there is nothing there to see. The content was multiplied at render time, then disappeared when the page closed.
To see it from the command line, I had to simulate the context of a single post page correctly; running it bare would not reproduce it:
# build the single-post context first, then run the content filter chain
$q = new WP_Query(['p' => $id, 'post_type' => 'post', 'posts_per_page' => 1]);
$GLOBALS['wp_query'] = $q; $GLOBALS['wp_the_query'] = $q;
$q->is_single = $q->is_singular = true; $q->is_home = false;
$q->the_post();

apply_filters('the_content', $content);   # run bare and it stays clean; run it like this and it expands
The first three measurements all produced the wrong list
Knowing one post was broken is one thing. Knowing how many more were broken is another, and I measured it wrong three times before I got it right.
First try: I thought I could simply read the post, rebuild the block structure, and write it back, and the system would normalize itself. It did not. That rewrite preserved the mismatch, and the heaviest post still expanded 8.8 times. One hour spent on an assumption I had not checked.
Second try: I counted the section headings visible on the page, and treated any post with at least twice the original number of sections as broken. That returned 64 posts. Wrong, because the interface always adds four headings from the related-post block at the bottom of the page. A post with only four sections shows up as eight — exactly double — and got flagged by mistake.
Third try: I counted how many times the post’s first section heading appeared on the page, and treated three or more appearances as broken. That returned about 240 posts. Also wrong, and even more seriously wrong: a normal heading already appears three to four times on the page — once in the table of contents, once in the real title tag, once in the image description, and once in the caption line under the image.
All three had the same flaw: they counted something the interface is allowed to add on its own. If you count something you do not control, the number you get is the interface’s number, not the post’s. I ran into the same kind of problem in another case, when I guessed the source of layout shift wrong four times in a row.
The only measurement left after the first three were rejected
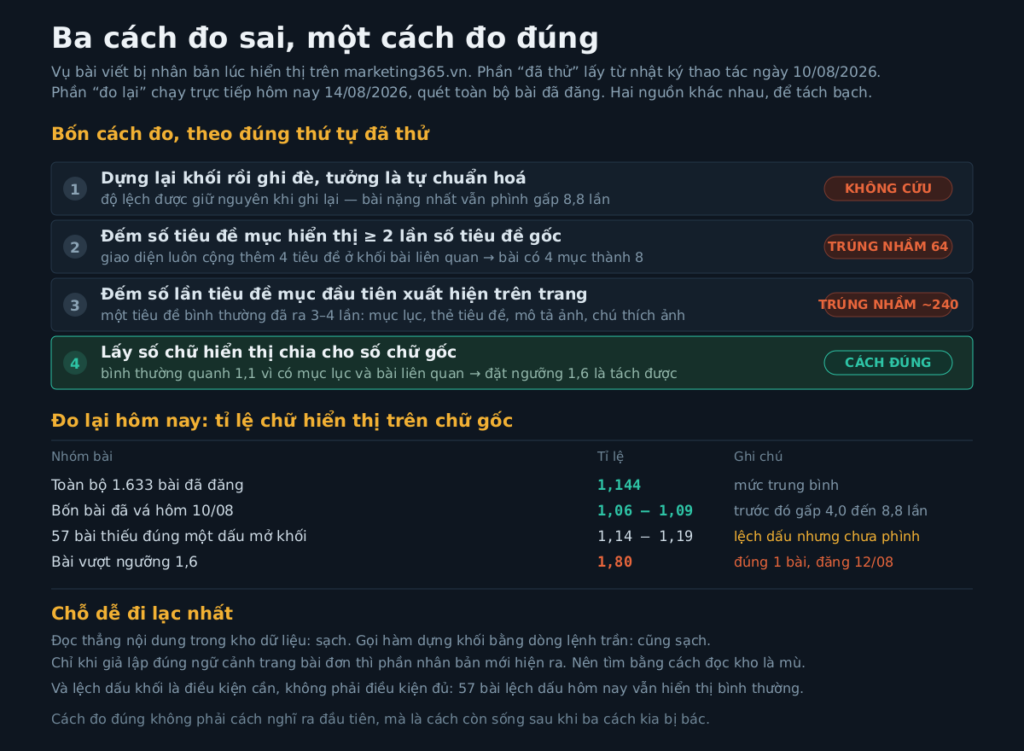
The method that worked was to throw out everything countable and keep only one ratio: displayed words divided by original words.
On a normal post, this ratio sits around 1.1 — the extra comes from the table of contents and the related-post block, meaning interface content added on top, and it is added consistently across posts. On duplicated posts, the ratio jumps to 4 to 9. The gap between 1.1 and 4 is wide enough that the threshold could have gone almost anywhere; I chose 1.6.
Scanning all published posts with that threshold returned exactly four posts. No misses, no false positives — and when I checked each one by hand, all four were genuinely broken.
For comparison: the second method returned 64 posts, the third returned 240, and the fourth returned 4. Same site, same day.
The culprit: missing block closers
Post content in WordPress is marked up with hidden opening and closing pairs inside the content, one pair per block. The heaviest post had 24 list-block openings but only 11 closings.
When WordPress renders a page, it runs the content through a chain of filters. One of those steps reads the block structure and writes it back out. When it encounters a mismatch, it does not throw an error — it writes out a version longer than the input. After a few passes through that path, the post becomes nine times larger.
The fix was suspiciously short: remove all block markup tags from those four posts.
preg_replace('/<!--s*/?wp:[^>]*?-->/s', '', $content)
After the patch, the ratio returned to 1.05 to 1.08. The displayed text did not change by a single character, and the number of paragraphs, lists, images, and section headings stayed the same. Readers saw no difference, except that the post no longer repeated itself.
One detail I checked afterward and was glad I checked: this bug existed before that day, and it was not caused by anything I did. Rebuilding each saved version of the post and measuring it showed that one post had already expanded 4x since 24/06, and another 6.2x since 10/07. If I had not checked the older saves, I would have wrongly concluded that I had just broken it myself.
Once the render-time duplication was fixed, a second layer appeared
Once the render-time duplication layer was removed, the layer underneath became visible: all four posts still contained FAQ blocks repeated verbatim two to five times inside the original content. This was exactly the kind of bug I had cleaned up in an earlier round and thought was already gone — I wrote about that separately in 43 Posts Repeated Themselves, One Repeated Five Times. These four slipped through because the render-time duplication layer had been hiding them.
Cleaning three of them was straightforward: they lost 3,725, 4,628, and 2,556 words respectively. I stopped on purpose with the fourth. After cleanup, it was left with only about 45% of its previous word count, turning it into a very thin post. What it needed was not cutting, but rewriting. Cutting it down to make the numbers look clean and leaving an empty post behind would have improved the spreadsheet, not the reader experience.
Today’s recheck, and what I still owe
On 14/08/2026, before writing this article, I reran the measurement across all 1,633 published posts:
- Average ratio: 1.144. Exactly as expected from interface content added automatically.
- The four patched posts: 1.06 to 1.09. The fix held after four days.
- Posts above the 1.6 threshold: exactly one, with a ratio of 1.80. It was the post published on 12/08, the same post with repeated content mentioned above.
And one number I do not like: when I scanned block markup across those 1,633 posts, 57 posts were missing exactly one opening tag, mostly in the reference section at the end of the post, all published from 27/07 onward. That means the automation process is still generating mismatched markup; I have only cleaned up the aftermath, not stopped the source.
The interesting part is that those 57 posts measured between 1.14 and 1.19 — they still looked normal on the page. In other words, mismatched markup is a necessary condition, but not yet a sufficient one, for a post to blow up; it has to be the right kind of mismatch in the right place. I do not yet know where that boundary is, and I am writing it down exactly that way instead of guessing a neat conclusion.
Three things I took away from this case:
- Check where the reader actually looks. A clean database does not mean a clean page.
- Do not count things the interface is allowed to add on its own. My first three measurements failed for exactly that reason.
- Before blaming yourself for a bug you just caused, check the older saves. This one had existed for a month and a half already.
The numbers in this article were measured on marketing365.vn, and each date is written next to the number it belongs to. The 1,633 posts and the 1.144 ratio are from 14/08/2026 — measure again at another time and you will get different results, because the site still publishes every day.