Contents
- AI agents, tokens and verifiable evidence are creating a new workflow channel
- Token Copilot and the Lean proof corpus are forcing marketing teams to work differently
- Agent loops are turning distribution into a cost-and-trust problem
- Vietnamese marketers need to price tokens and evidence into the AI distribution channel
- Measure tokens and lock publishing rights before handing work to agents
- References
AI agent does not just replace a paragraph of writing. It creates a new workflow channel, where the cost of reaching users depends on how many times the machine rereads context and how trustworthy the evidence behind the output is. For Vietnamese marketers, this is the moment to measure tokens, task logs and approval rights instead of only asking which model writes better.
Key points
- Context compression can turn repeated history into a controllable cost inside the coding agent loop.
- The Lean proof corpus shows that agents need structured data and a mechanism to stop the machine from asserting what has not been proven.
- Distribution through agents will be cheaper when excess context is reduced, but it is only trustworthy when evidence and checkpoints are preserved.
- Vietnamese marketing teams should test narrow tasks, record tokens and require agents to present evidence before opening publishing access.
AI agents, tokens and verifiable evidence are creating a new workflow channel
Two developments in the source point to the same change: an agent’s value does not lie only in the model, but in how the work loop is organized. One post describes SOMA being attached to GitHub Copilot to compress files, tool traces and old state before sending them into the model; DeepSeek V4 Pro was introduced with about 10% token savings in the Early Access program. Source on SOMA and Copilot.
On the other side, Jeffrey Emanuel describes a formal proof repository in Lean with more than 12 million lines of proof code and more than 29,000 theorems, while also building a skill to make agents more cautious about calling a proposition proven. Source on Lean and the verification skill. One side reduces context that is no longer needed; the other raises the quality of the checkpoint. Together, they show that automation has to be designed around the loop, not just around the answer.
Token Copilot and the Lean proof corpus are forcing marketing teams to work differently
The update block below records only the tools, documents and numbers stated directly in the source material. They are not yet proof that every marketing agent will achieve the same results.
SOMA in GitHub Copilot: content teams need to track tokens by task
SOMA is described as a context compression layer that can process files, tool traces and old state before sending them to the model. The material introduces the use of DeepSeek V4 Pro in Copilot with about 10% token savings, along with a 5 USD credit for Early Access participants and no platform fee during this period. Details from the SOMA material. For marketing, what needs to be recorded is not just total runs, but tokens for each brief, each revision, each tool call and each time the agent rereads documents.
The Lean formal proof corpus: automated content must come with verified conditions
The proof corpus is described as containing more than 12 million lines of code and more than 29,000 theorems. The accompanying skill focuses on not accepting a proposition as true simply because the agent just wrote it; the agent has to rely on Lean’s structure and verification mechanism. Description of the Lean corpus and skill. Marketing teams can draw a similar lesson: brief, claim, source, usage conditions and approver should be separate fields, rather than leaving everything inside one long prompt.
Agent loops are turning distribution into a cost-and-trust problem
Repeated context turns every reach into a cost that can be cut
In coding agents, session history, repeated tool results and old state make token counts rise with the length of the loop. Context compression is therefore not just a technical trick; it changes the price of a task that keeps running. Source on context cost. The Lean proof corpus shows the reverse side: when a task requires many reasoning steps, data and checking rules must be organized so the agent does not skip an important condition. Source on the proof corpus.
For marketing, “distribution through agents” is not just a chatbot answering users. It can be a chain of briefing, document retrieval, variant generation, claim checking and then handing content to a publishing point. Every reread of context is part of the reach cost. Cutting excess context lowers running costs, but cutting the wrong source or brand condition can make content cheaper while increasing risk.
Structured evidence decides which content is allowed to run on its own
The Lean skill is described with “epistemic humility”: the agent must distinguish what has been proven from what has only been stated, thanks to mechanical and structural safeguards. Source on the verification mechanism. At the same time, context compression in Copilot creates a requirement to keep only the history needed for the next task, rather than sending the entire working session into the model. Source on keeping the necessary context.
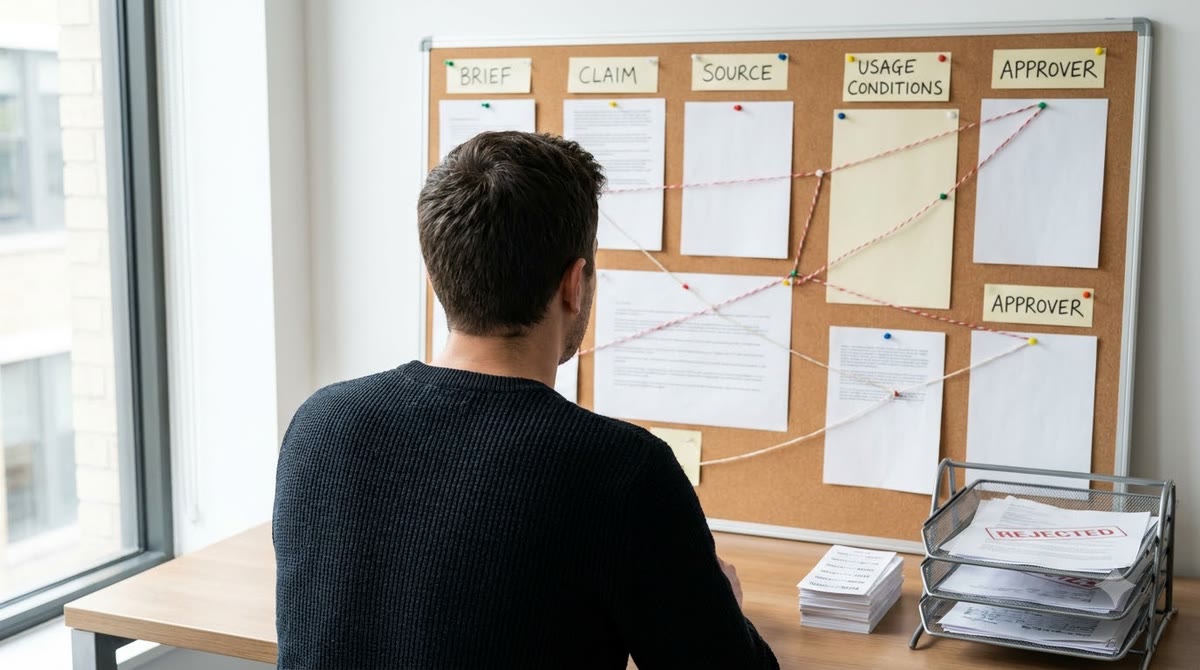
These two requirements form a rule for content distribution: an agent should only move output to the next step when enough evidence remains to verify it. For advertising, that could mean a claim that has been cross-checked. For email, it is the recipient file and sending conditions. For SEO, it is the source, query target and the person responsible for approval. The more automated the channel, the clearer the checkpoint must be.
Vietnamese marketers need to price tokens and evidence into the AI distribution channel
Vietnamese businesses often begin automation with high-frequency tasks: writing ad variants, classifying leads, generating reports or answering repeated questions. These tasks are suitable for testing, but the cost is not only the subscription price. It also lies in how many times the agent reads documents, calls tools, fixes errors and waits for approval.
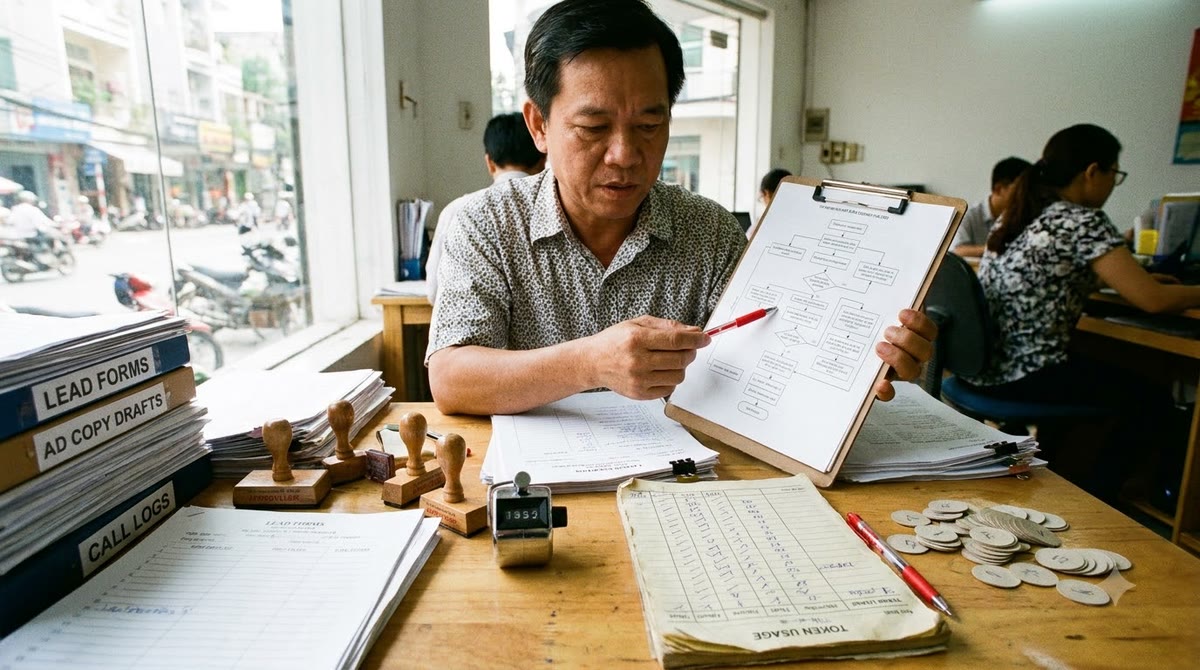
A practical way to test is to create a table for each workflow: input, number of loops, tokens, reviewer time, return rate and the evidence that must be kept. If context compression is used, the team needs to check two separate outcomes: how much running cost falls and whether important information is being missed. If a skill or structured data corpus is used, the team needs to check whether the agent can distinguish “verified” from “no basis yet.”
This is also the difference between internal automation and customer-facing distribution. A mistake in a draft can be fixed. A mistake that the agent sends on its own through email, advertising or customer service becomes a brand problem. That is why the Vietnamese market should not buy self-running access just because the demo is fast; that right needs to be tied to logs, cost thresholds and an approver.
Measure tokens and lock publishing rights before handing work to agents
- Choose one narrow workflow, such as generating ad variants from a standardized brief, then record tokens and tool-call counts for each run.
- Separate mandatory context from history that can be dropped: product information, allowed claims and legal conditions should always have their own record.
- Set an approval point before the agent sends content to a live channel; the agent can suggest and check, but it should not publish on its own before conditions are met.
- Require each output to include source, verification status and the responsible person. Expand the budget only when running cost and error rate are measured on real tasks.
See more marketing analysis and how-to guides at https://marketing365.vn.
Follow more analysis from Marketing365 to stay updated on the latest marketing trends.
Read more articles in the same category AI Developments.
References
- Coding agents, context compression in GitHub Copilot and SOMA Early Access
- Anthropic’s Lean formalization, proof corpus and epistemic humility skill