Contents
- Signals from new AI models are converging on task-based budgeting
- New model capabilities are forcing marketing teams to work differently
- Task-based budgets are changing because of run cost, output, and control rights
- Astra and GPT-6 are unconfirmed: should budgets wait to be locked?
- Vietnamese businesses read new AI models through data and deployment cost
- A task-based AI model checklist before expanding budget
- References
New AI models are expanding in several directions at once: image editing by instruction, long-context processing, multimodal use, code support, and connections to machines. For Vietnamese marketers, the point to watch is not which model draws the most attention, but how budgets will shift from buying access to paying for each task, each output, and each level of control.
- Key point: Model value is being pulled down to the level of specific jobs, no longer resting on benchmark scores alone.
- A cheaper model does not necessarily lower total cost if it requires many steps of checking, fixing, and security.
- Multimodal capability, long context, and image editing open up more output, but they also raise moderation requirements.
- Marketers should test by measurable tasks, keep human approval in place, and avoid setting a large budget based on rumors.
Signals from new AI models are converging on task-based budgeting
Six developments in the source material show that the market is not just chasing one all-purpose model. Qwen3.8-Flash has 125B/6B versions, 1M context, and multimodal support in OpenCode Go; Hy4 preview is described as having internal scores similar to some Flash models but at a lower cost per task. On the image side, the V8.2 edit model supports up to four reference images, brush-based inpainting, and outpainting. At the same time, the Model Hardware Standard aims to let agents communicate with physical devices. Together, these pieces push budget questions closer to everyday work.
That matters for marketing because cost does not stop at model calls. Teams also pay for prompt writing, variant generation, brand review, error correction, data storage, and incident handling. A model with a low price per task only creates real value when it reduces the total number of steps or helps the team produce more outputs that meet standards.
New model capabilities are forcing marketing teams to work differently
This section only records the capabilities explicitly stated in the sources, then turns them into operational questions for marketing teams.
V8.2 edit model: less effort fixing assets, more need for brand approval
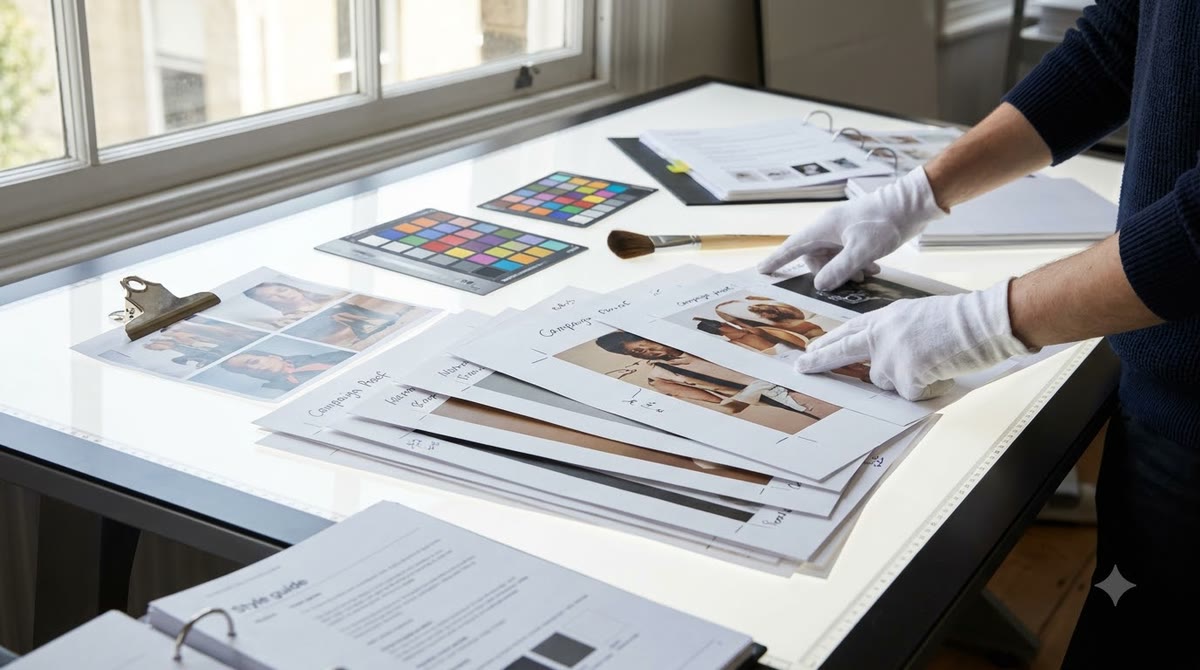
The model described by Midjourney can edit images by instruction, generate images from up to four reference images, perform inpainting, outpainting, personalization, moodboards, and srefs (Midjourney source). For marketing teams, this is a capability set well suited to expanding creative variants, adjusting layouts for each channel, and testing multiple art-direction paths. It does not replace approval: the easier it becomes to generate many versions, the more the team needs a checklist for logos, colors, characters, claims, and image usage rights.
Qwen3.8-Flash: 1M context and multimodal change how long briefs are handled
Qwen says the model has a 125B/6B configuration, 1M context, and multimodal support, and that it has been added to OpenCode Go (Qwen source). In marketing work, long context can help bring briefs, guidelines, product data, and multiple reference documents into one processing flow. However, marketers still need to check the input data, limit access rights, and understand how the model extracts information before using it for external content.
Model Hardware Standard: when agents touch devices, workflows need stop points
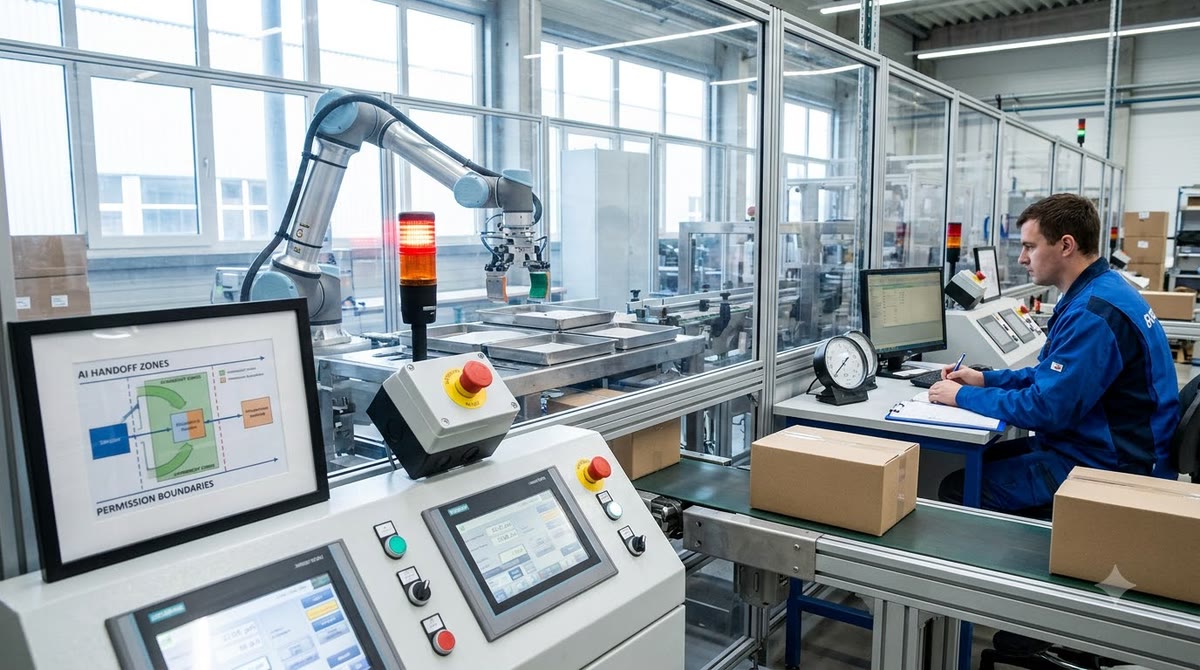
Information relayed by CoinMarketCap says Anthropic announced the Model Hardware Standard so agents can operate and communicate with physical machines such as scientific or production equipment (reposted source). For marketing, the closer application may be connecting agents to printing systems, sample storage, filming equipment, or content production workflows. Every new connection needs a clear definition of what the agent can read, how far it can act, and who approves actions with real cost.
Task-based budgets are changing because of run cost, output, and control rights
Cost per task: a cheap model only helps if it also cuts error-fixing steps
Hy4 preview is described by a Command Code user as reaching a level similar to DeepSeek V4 Flash and GLM 5.3 Flash in internal benchmarks, while being cheaper than GLM on a per-task basis (Hy4 source). Qwen3.8-Flash, meanwhile, brings 1M context, multimodal support, and two scales, 125B/6B, into one code tool (Qwen source). These two signals suggest a different way to budget: measure the price of one output that meets standards, not just the price of one request.
For example, a landing page creation workflow needs to count content generations, revisions, review time, and approver cost. If a model is cheap but creates many brand errors or product inaccuracies, the savings on API usage can be erased by labor costs.
Creative output: more formats also mean higher moderation costs
The edit capability with four reference images and brush-based inpainting in V8.2 can shorten image variant production (Midjourney source). Qwen3.8-Flash’s long context and multimodal support also help process multiple document types in one flow (Qwen source). When output increases, the budget should not go entirely to tools. A separate allocation is needed for brand review, claim checks, image rights, and version tracking.
Agent permissions: the more it can do on its own, the wider the incident cost
The Model Hardware Standard brings agents closer to physical machinery (reposted source). Another warning about OpenClaw says that incorrect permissions, even inside a container, can expose files, credentials, or external services; the article also mentions incidents involving autonomous agents (Dr Altcoin source). The two sources do not prove the same product or the same level of risk, but they are enough for marketers to include security costs, audit logs, and approval steps in the model equation.
Astra and GPT-6 are unconfirmed: should budgets wait to be locked?
Is early September enough to set a launch budget?
A Token Gremlin post says Sam Altman is expected to appear at the G20 Innovation Ministerial in North Carolina on September 1–2 and may preview the next direction in AI development. The post stresses that this is not confirmation that OpenAI will launch Astra or GPT-6 at the event; the Axios and Reuters references also appear only as citations inside the post, not as independent confirming documents in this dataset (Token Gremlin source). This is a timing guess, not a product commitment.
What is usable: Marketing teams can follow official announcements, but they should not move the entire budget or cancel current tests. Set up two scenarios: continue with the model whose cost and quality are already measurable; shift budget only when the model, price, access rights, and data conditions are clear.
Vietnamese businesses read new AI models through data and deployment cost
In Vietnam, many marketing teams work with Vietnamese language, internal customer data, and budgets that must be justified campaign by campaign. So 1M context or multimodal capability only matters when the tool handles Vietnamese briefs correctly, preserves guidelines, and does not expose data.
A suitable testing method is to choose three tasks with clear outputs: generating ad variants, resizing assets for channel formats, and summarizing briefs into content plans. Measure completion time, revision rate, factual errors, cost per output that meets standards, and approval time. For agents, add the number of actions requiring human approval and the number of times the system accesses out-of-scope resources.
A task-based AI model checklist before expanding budget
- Split test budgets by task instead of buying a large package just because the model has strong benchmarks.
- Use the same brief, guidelines, and approval criteria to compare the cost of each output that meets standards.
- Keep human approval for external content, credentials, customer data, and any action with physical impact.
- Expand only after the dashboard records enough quality, error-fix cost, approval time, and access traces.
See more marketing analysis and how-to guides at https://marketing365.vn.
Follow more analysis from Marketing365 to stay updated on the latest marketing trends.
Read more articles in the AI developments category.
References
- Sam Altman will appear at the G20 Innovation Ministerial in North Carolina on September 1–2
- We’re gonna start testing our first V8.2 edit model today
- Anthropic announced the Model Hardware Standard
- Hy4 preview just launched
- Concern about promoting OpenClaw and autonomous AI agent security
- 125B/6B, 1M context, multimodal: Qwen3.8-Flash