Contents
- AI infrastructure is shifting the race from models to serving capacity
- Speculative decoding and mainstream GPUs are forcing marketing teams to work differently
- Bargaining power now sits in inference cost and model distribution
- Vietnamese businesses need to view AI infrastructure through real usage rates
- Measure cost per task before expanding the AI budget
- References
AI infrastructure is becoming the deciding factor in bargaining power between businesses and model vendors, not just because of chip counts. For Vietnamese marketers, this shift directly affects testing budgets, the speed of bringing AI into workflows, and the ability to keep services running as demand grows.
The article’s argument is this: the advantage no longer lies only with the model that scores highest on benchmarks, but with the system that can serve many requests at measurable cost and with enough distribution.
Key points
- Inference cost depends on both token generation speed and how hardware is utilized.
- Speculative decoding and models that can run on mainstream GPUs lower the barrier to AI adoption.
- Large compute scale only matters when paired with revenue, utilization, and serving margins.
- Vietnamese businesses should buy serving capacity by workflow, not by chip count or a single score.
AI infrastructure is shifting the race from models to serving capacity
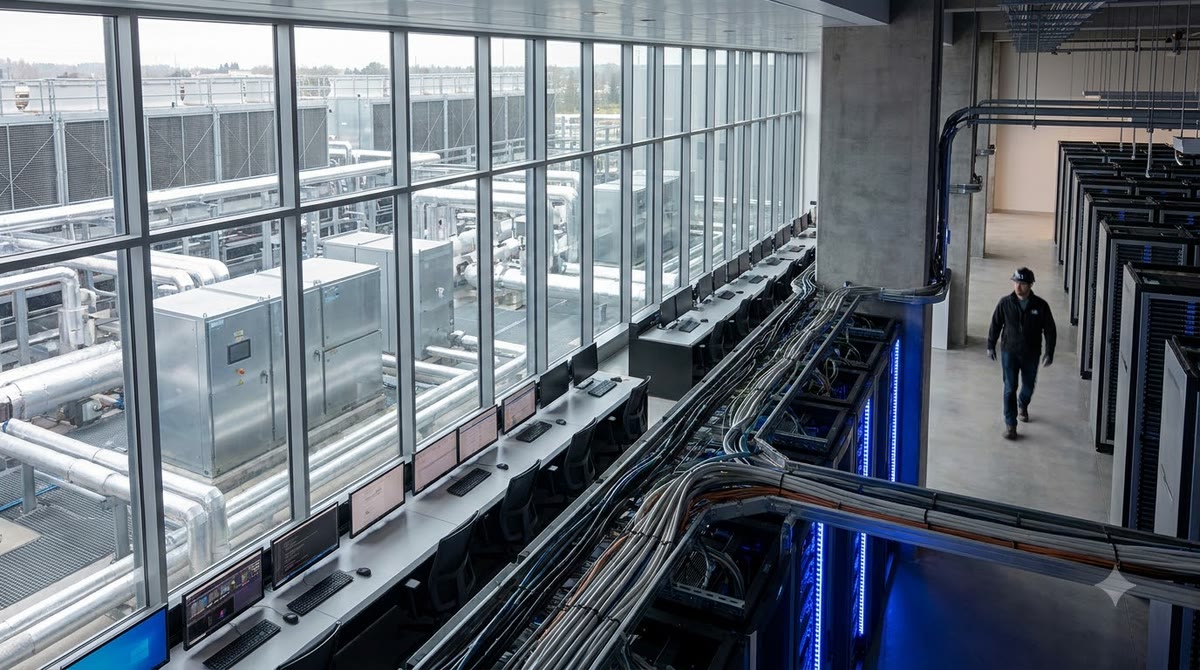
Three developments in the sources point to the same shift. The speculative decoding guide by Lily Zhang and Madison Kanna describes a common LLM bottleneck: the model generates one token at a time, which limits inference speed. Meanwhile, the analysis of Anthropic shows the game has moved to gigawatt-scale compute, multiple types of hardware, and very large capacity commitments. (Source on speculative decoding; Anthropic compute analysis)
At the other end, a Bittensor subnet put the Qwen 3.8 27B checkpoint on Hugging Face and recorded more than 500,000 downloads; the model can run on an RTX 5090. That number does not prove 500,000 machines are running the model, but it does show that distributing models through user hardware can create a different access channel from relying entirely on data centers. (Subnet activity roundup)
Speculative decoding and mainstream GPUs are forcing marketing teams to work differently
The updates below only record technologies or figures stated directly in the materials. What they have in common is that they change how a marketing team evaluates an AI tool.
Speculative decoding: measure serving speed, not just the model
Speculative decoding uses a small model to propose token sequences, then a large model checks those proposals. The method is meant to shorten response generation time in autoregressive tasks. Lily Zhang and Madison Kanna’s material calls it an important topic in the LLM stack and says the technique has been used across multiple hosted LLM services. For marketing, the metric to watch does not stop at output quality; latency, requests served per hour, and cost per task also need to be on the dashboard. (Speculative decoding material)
A checkpoint running on RTX 5090 expands testing beyond server clusters
The Qwen 3.8 27B checkpoint is described as running on an RTX 5090 and having passed 500,000 downloads on Hugging Face. This is a sign that models can be distributed to developers and testing teams with consumer hardware, not proof of final product quality. Marketing teams can use this kind of model for prototyping, generating test data, and checking internal workflows before paying for API usage at scale. (Checkpoint and download information)
Multi-hardware compute demands workload-based serving comparisons
The Anthropic analysis notes that Claude uses AWS Trainium, Google TPU, and Nvidia hardware, along with a plan for up to 2 GW of AMD systems starting in 2027. That detail shows the same AI demand can be served on many chip types. Marketers do not need to choose chips at the technical level, but they do need to ask vendors to disclose latency, load limits, downtime, and per-task pricing instead of only naming the model. (Anthropic hardware analysis)
Bargaining power now sits in inference cost and model distribution
Inference cost turns token speed into a buying condition
LLMs generate one token at a time, so every improvement in serving speed can affect budgets as usage grows. Speculative decoding addresses exactly this bottleneck, while Anthropic’s large compute plans show that vendors must keep buying more capacity to meet demand. Put together, the two sources show buyers have stronger grounds for negotiation if they ask for pricing tied to response time and actual output, rather than accepting a price list detached from performance. (Speculative decoding source; Anthropic compute source)
Models running on mainstream hardware lower the upfront testing fee
The checkpoint that can run on an RTX 5090 and the inference optimization technique both point to a change in market structure: model testing does not have to start with a large cloud contract. A team can check prompts, data, and approval flows on a local machine, then move only the tasks that have proven value to paid infrastructure. This increases buyer choice, even if it does not replace the need for security, uptime, and scalability. (Checkpoint source; Inference optimization source)
Large compute commitments do not automatically mean good serving margins
The Anthropic analysis says at least 14.8 GW of compute has been arranged and potential costs could reach 517 billion USD over a decade, while also stressing that utilization and serving margins must be considered. This is important when reading infrastructure claims. A model backed by many chips can still put pressure on pricing if real demand is not high enough. Conversely, a widely downloaded model running on mainstream GPUs can create competitive pressure at the distribution layer. (Source on compute, revenue, and serving margins; Source on model distribution)
Vietnamese businesses need to view AI infrastructure through real usage rates
The Vietnamese market is unlikely to gain an advantage by simply buying access to an expensive model and leaving the team to figure out how to use it. Many marketing teams need to start with tasks that have clear traffic: generating content variants, classifying feedback, supporting customer research, or checking campaign data.
For lighter tasks, a model running on mainstream GPUs may be suitable for the testing phase, but businesses still need to check data rights, security, and operational reliability. For tasks that require fast responses or have heavy traffic, multiple vendors should be compared based on cost per task, response time, and service commitments. This is how diversity in chips and models becomes choice, rather than a hard-to-evaluate list of technologies.
Measure cost per task before expanding the AI budget
- Choose one specific marketing workflow and record the number of model calls, response time, revision rate, and cost per output.
- Run the same test set on a cloud model and a model that can operate on mainstream GPUs; do not conclude from benchmark scores alone.
- Bring questions about uptime, load limits, hardware used, and pricing method into the tool procurement process.
- Increase the budget only when real usage rate, output quality, and total spend are all tracked on the same dashboard.
See more marketing analysis and guides at https://marketing365.vn.
Follow more analysis from Marketing365 to stay updated on the latest marketing trends.
Read more articles in the same category AI Developments.
References
- Introducing Speculative Decoding: How It Evolved, When It Stays Lossless, and What’s Next
- While people argue whether $TAO is a real AI play, one of its subnets put a model on 500,000 machines
- The Information just reported Anthropic has lined up at least 14.8 GW of new compute since October